Checklist Bulgaria selection 2026 National Competition in AI, final (in-person) round · Task 1
Wild Blueberry Yield Prediction
Bulgarian title: Прогнозиране на добива от дива боровинка
Predict wild blueberry yield from climate, pollinator and fruit features.
The task
The target is the wild blueberry yield. Features include clone size, densities of honeybees, bumblebees, Andrena and Osmia bees, upper and lower daily temperature ranges during flowering (maximum, minimum, average), total and average raining days, fruit set, fruit mass and seeds per fruit.
Contestants select features and train a regression model; kNN, gradient boosting and a multilayer perceptron are given as examples, but other algorithms may be used.
Abridged and translated by SOTA from the official Bulgarian materials. The official statement has the exact rules, and it wins wherever this summary differs.
In English
This task was published in Bulgarian. SOTA translated it into English on 17 September 2026. Only the words changed in the notebooks: markdown, code comments, messages and printed output. The code, file names and paths are the original's, so a translated notebook runs with the original data.
Read the task notebook in English
Wild Blueberry Yield Prediction
import numpy as np
import pandas as pd
import matplotlib.pyplot as plt
import seaborn as sns
Task
The goal of the task is to predict the yield of wild blueberry on the basis of climatic and ecological indicators. Your task is to select suitable features and to train a regression model. kNN, Gradient Boosting and Multilayer Perceptron are given as example algorithms, but you may also choose another algorithm.
Data
Target variable:
- yield- wild blueberry yield
Features
- clonesize (m²) – average size of the blueberry clone
- honeybee (bees/m²/min) – density of honeybees
- bumbles (bees/m²/min) – density of bumblebees (bumblebees)
- andrena (bees/m²/min) – density of mining bees (Andrena)
- osmia (bees/m²/min) – density of mason bees (Osmia)
- MaxOfUpperTRange (°C) – highest daily temperature (upper bound) during bloom
- MinOfUpperTRange (°C) – lowest daily temperature (upper bound)
- AverageOfUpperTRange (°C) – average daily temperature (upper bound)
- MaxOfLowerTRange (°C) – highest daily temperature (lower bound)
- MinOfLowerTRange (°C) – lowest daily temperature (lower bound)
- AverageOfLowerTRange (°C) – average daily temperature (lower bound)
- RainingDays (days) – total number of days with rainfall during bloom
- AverageRainingDays (days) – average number of days with rainfall during bloom
- fruitset (%) – percentage of successfully set fruits out of the total number of flowers
- fruitmass (mg) – average mass of one fruit (milligrams)
- seeds (count/fruit) – average number of seeds per fruit
Scoring
The submitted results will be evaluated using the mean absolute error (MAE),
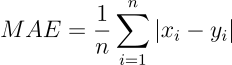
where each represents the predicted target, represents the actual value, and is the number of rows in the test set.
Submission file
For each identifier in the test set you must predict the target yield. The file must contain a header row and have the following format:
id,yield
15289,6025.194
15290,1256.223
15291,357.44
etc.
df = pd.read_csv("train.csv", index_col=0)
df.shapedf.head()# Target variable
target = df['yield']
# Features
features = df.drop(columns=['yield'])# Add or remove features hereModels
# Loading the test data

X_test = pd.read_csv("test.csv", index_col=0)
# Loading the required modules
from sklearn.preprocessing import StandardScaler
from sklearn.model_selection import GridSearchCV
from sklearn.pipeline import Pipeline
from sklearn.neural_network import MLPRegressor
from sklearn.model_selection import cross_val_score
from sklearn.neighbors import KNeighborsRegressor
from sklearn.metrics import make_scorer, mean_absolute_error
from sklearn.ensemble import GradientBoostingRegressor
from sklearn.model_selection import train_test_split# Scoring function
mae_scorer = make_scorer(mean_absolute_error, greater_is_better=False)K-Nearest Neighbors Regression (KNN)
pipe_knn = Pipeline([
    ('scaler', StandardScaler()),
    ('knn', KNeighborsRegressor())
])
param_grid_knn = {
    # add hyperparameters here
    'knn__n_neighbors': [3],
    'knn__weights': ['uniform'],
    'knn__metric': ['euclidean']
}
gs_knn = GridSearchCV(
    pipe_knn,
    param_grid_knn,
    cv=5,
    scoring=mae_scorer,
    n_jobs=-1,
     return_train_score=True
)
gs_knn.fit(features,target)
Neural Network Regression (MLP)
pipe_nn = Pipeline([
    ('scaler', StandardScaler()),
    ('nn', MLPRegressor(max_iter=3000, random_state=42))
])
param_grid_nn = {
    # add hyperparameters here
    'nn__hidden_layer_sizes': [(64, 64)],
    'nn__activation': ['relu'],
}
gs_nn = GridSearchCV(
    pipe_nn,
    param_grid_nn,
    cv=5,
    scoring=mae_scorer,
    n_jobs=-1,
    verbose=2,
    return_train_score=True
)
gs_nn.fit(features, target)
Gradient Boosting Regression
gbr = GradientBoostingRegressor(random_state=42)
param_grid_gbr = {
    # add hyperparameters here
   'n_estimators': [5],
    'max_depth': [10],
}
gs_gbr = GridSearchCV(
    estimator=gbr,
    param_grid=param_grid_gbr,
    cv=5,
    scoring=mae_scorer,
    n_jobs=-1,
    verbose=2,
    return_train_score=True
)
gs_gbr.fit(features, target)
## Choose the best model here
best_model = gs_nn
predictions = best_model.predict(X_test)# Saving the predictions to the file Task_1_USER_ID_submission.csv
# REPLACE WITH YOUR NUMBER!
USER_ID = ''
submission = pd.DataFrame({
'id': X_test.index,
'yield': predictions
})
submission.to_csv(f'Task_1_{USER_ID}_submission.csv', index=False)Translated by SOTA. The Bulgarian original is the official version and wins wherever the two differ. The notebook reads train.csv and test.csv, which are next to it in the original folder. The MAE formula is an image embedded in the notebook. If you organise this olympiad and would like the translation removed, email [email protected] and we will take it down.
At a glance
- You get
train.csvandtest.csv.- You submit
- CSV with header id,yield and a predicted yield for every test id.
- Scoring
- Mean absolute error (MAE).
- Format
- Final (in-person) round of Bulgaria's first National Competition in AI (school year 2025/2026), held on 28 February 2026 in Plovdiv (the organisers announced 28 Feb - 1 Mar 2026); the top 120 of the online first round (31 Jan 2026) were invited. Task 1.